Perplexity AI’s Sonar is an advanced multimodal AI assistant optimized for real-time, context-aware web search, synthesis, and conversational analytics. Designed for both professional and consumer workflows, Sonar combines fast, authoritative information retrieval with robust reasoning over retrieved documents.
Sonar demonstrates consistency in real-time information retrieval and source-backed answer quality. Its upward trend in query volume and user engagement signals strong market fit for knowledge-intensive workflows. The trade-off for rapid, cited answers is slightly higher latency compared to pure LLM chatbots, but with greater accuracy and transparency.
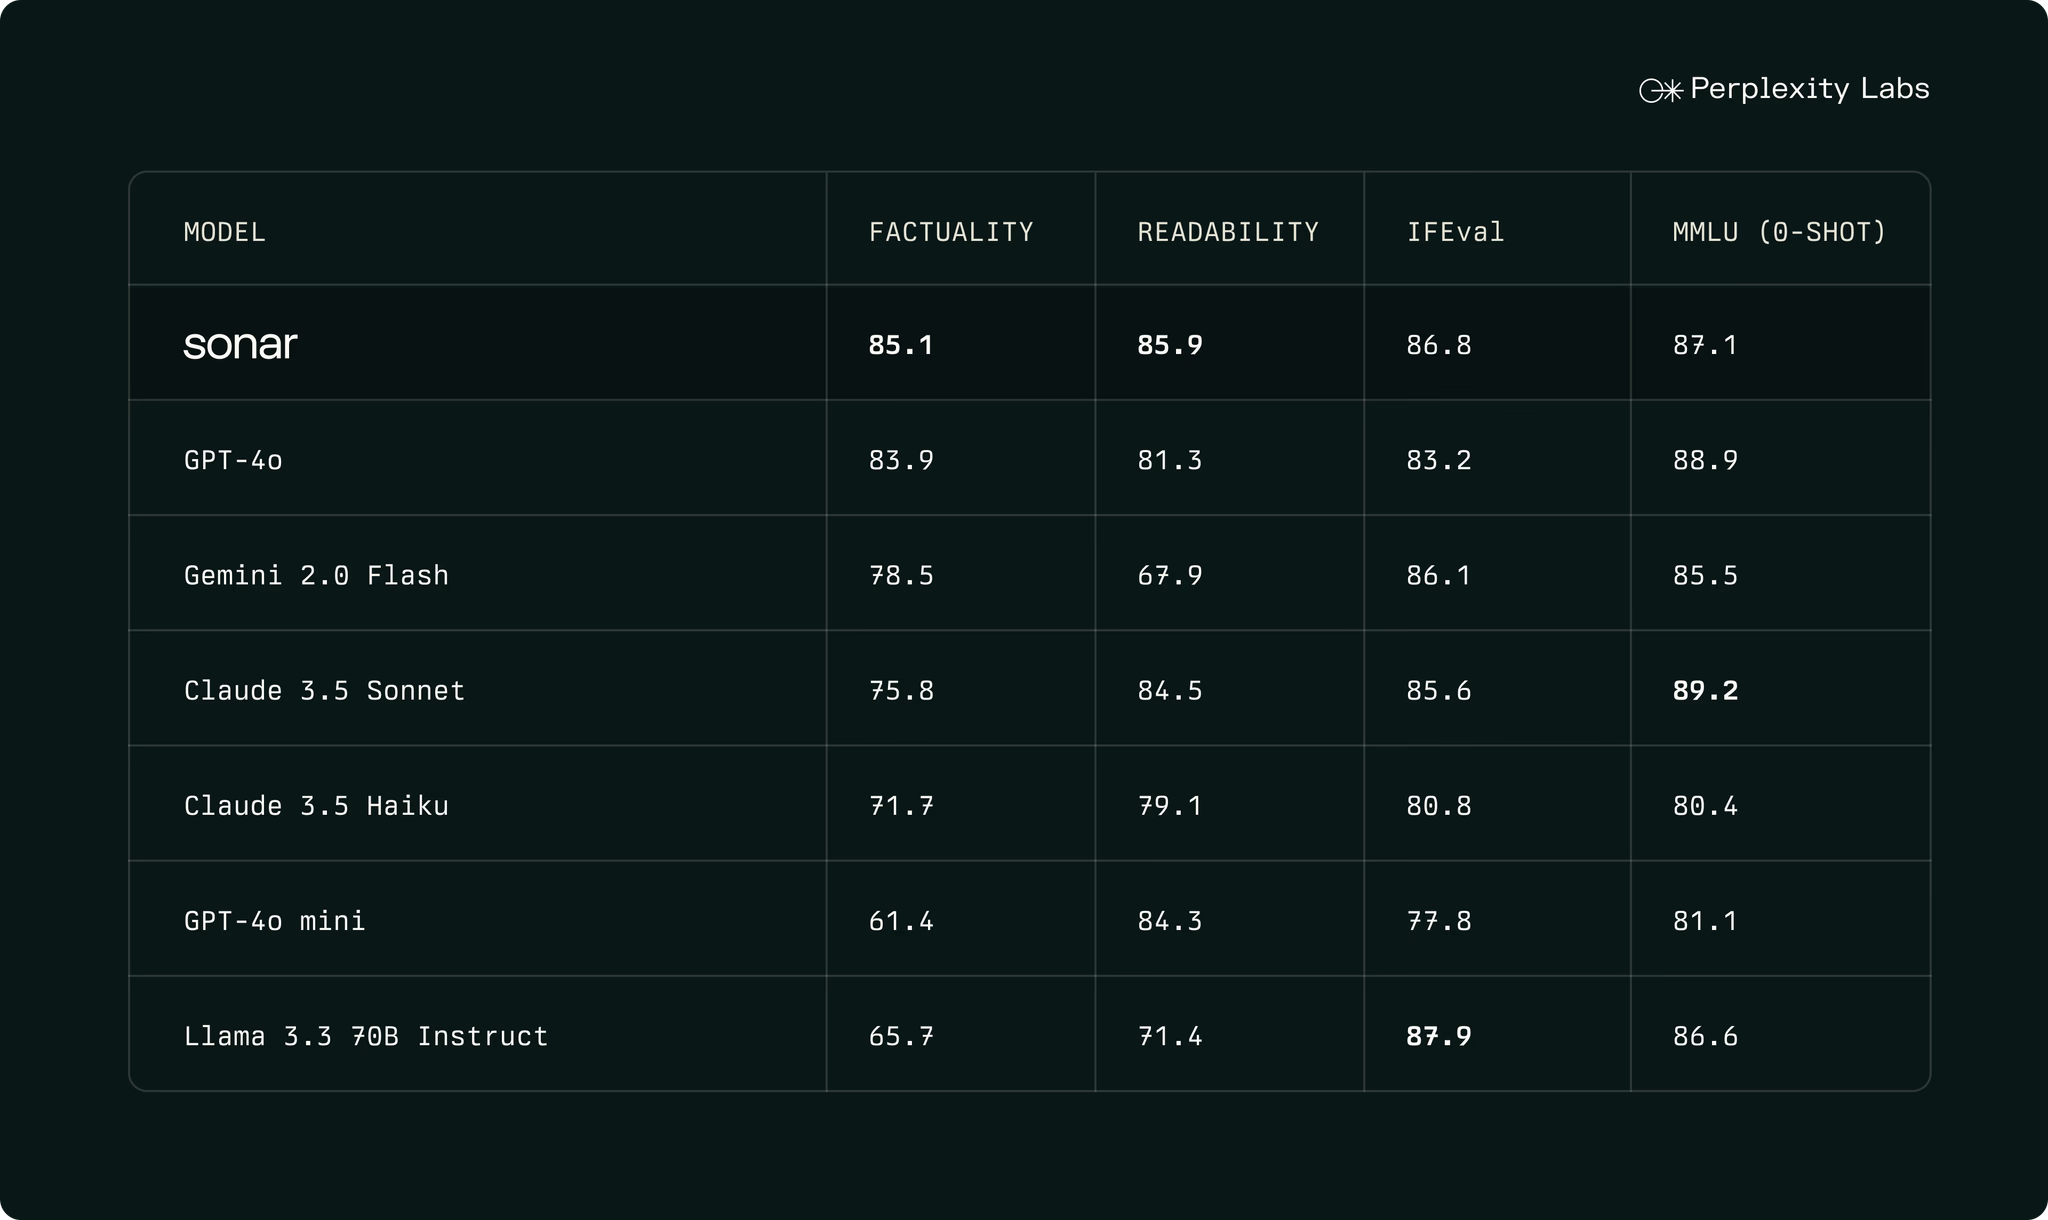
Perplexity Sonar API delivers authoritative outputs for information-dense workflows.
Vs. Claude 4 Opus: Sonar specializes in live, cited answers from the web, while Claude 4 Opus leads in autonomous coding, reasoning, and agentic workflows. Sonar is optimized for users who need answers grounded in the latest, most authoritative sources rather than long-context reasoning or code generation.
Vs. Gemini 2.5: Sonar emphasizes real-time search and synthesis; Gemini models offer broad multimodal capabilities and long-context reasoning but may not always surface citations or real-time data as explicitly.
Vs. OpenAI GPT-4: Perplexity Sonar is purpose-built for retrieval-augmented generation (RAG) and source transparency; GPT-4 is a generalist model, best for broad reasoning and creative tasks without built-in web sourcing.
Perplexity/Sonar specializes in real-time research, multi-source synthesis, and cited analytics, setting it apart for up-to-date, accurate, and verifiable answers. However, its limitations are equally distinctive:
Accessible via AI/ML API. Documentation: available here
Measured on the AI/ML API gateway across live traffic. Figures are medians unless stated. Last updated 2026-10-12.
import requests

r = requests.post(
    "https://api.aimlapi.com/v1/chat/completions",
    headers={"Authorization": "Bearer " + AIMLAPI_KEY},
    json={
      "model": "perplexity/sonar",
      "messages": [
        {
          "role": "user",
          "content": "Hello!"
        }
      ]
    },
)
print(r.json())
const r = await fetch("https://api.aimlapi.com/v1/chat/completions", {
  method: "POST",
  headers: {
    Authorization: `Bearer ${process.env.AIMLAPI_KEY}`,
    "Content-Type": "application/json",
  },
  body: JSON.stringify({
    "model": "perplexity/sonar",
    "messages": [
      {
        "role": "user",
        "content": "Hello!"
      }
    ]
  }),
});
console.log(await r.json());
curl -X POST https://api.aimlapi.com/v1/chat/completions \
  -H "Authorization: Bearer $AIMLAPI_KEY" \
  -H "Content-Type: application/json" \
  -d '{"model":"perplexity/sonar","messages":[{"role":"user","content":"Hello!"}]}'
OpenAI-compatible — swap the base URL and it works with your existing SDK.
| Type | Price |
|---|---|
| Input | |
| Output | |
| Benchmark | Score | What it measures | Source | Retrieved |
|---|---|---|---|---|
| Intelligence | 8.7 | Composite score across standardised reasoning, knowledge and problem-solving evaluations, measured independently by Artificial Analysis | Source | September 12, 2026 |
| Model | Input | Output | Context | Best for |
|---|---|---|---|---|
Sonar This page | Chat + assistants | |||
| Reasoning + agents | ||||
| Balanced coding + agents | ||||
| Long-context, multimodal & agentic workflows | ||||
| Reasoning + agents |
Sonar has a 128,000 tokens context window and can return up to 100,000 tokens.
Sonar takes image, text as input and returns text.
Use perplexity/sonar as the model id. Requests go to https://api.aimlapi.com/v1/chat/completions.
Sonar became available on September 9, 2025.
Sonar is priced at input $1.3 / 1M tokens, output $1.3 / 1M tokens.
Yes, Sonar can stream responses as they are generated.
Yes, Sonar accepts image input alongside text.
Sonar was built by Perplexity.
Sonar is a fast, search-augmented model grounded in real-time web data, suited for tasks that need up-to-date information.
No. Sonar can accept image inputs but only produces text output.
Yes. Web search is listed as one of Sonar's core capabilities.