Seedream 4 is ByteDance’s advanced AI model that unifies image generation within a single powerful platform. It delivers photorealistic images at 2K resolution in about 1.8 seconds and supports outputs up to 4K resolution, enabling rapid, high-quality content creation. The model accepts up to six reference images and can generate up to nine consistent images simultaneously, ideal for batch campaigns and storyboard workflows. It features natural language-driven editing, allowing users to add or remove elements easily without complex inputs, while maintaining strong character consistency. Seedream 4 supports bilingual prompts in Chinese and English, making it accessible for global and localized creative workflows.
Seedream 4 is built on ByteDance’s next-generation hybrid transformer architecture featuring a dynamic Mixture of Experts (MoE) design. This advanced architecture dynamically allocates computation at the token level, enabling ultra-low latency and high-quality image generation. The MoE layers provide efficient scaling, delivering 2K resolution outputs in roughly 1.8 seconds and supporting up to 4K ultra-high-resolution outputs.
This unified model supports text-to-image generation and batch creation within a single multimodal framework. It handles complex inputs, including natural language prompts, up to six reference images, and video frames, enabling rich multimodal reasoning and synthesis with strong semantic and prompt fidelity.
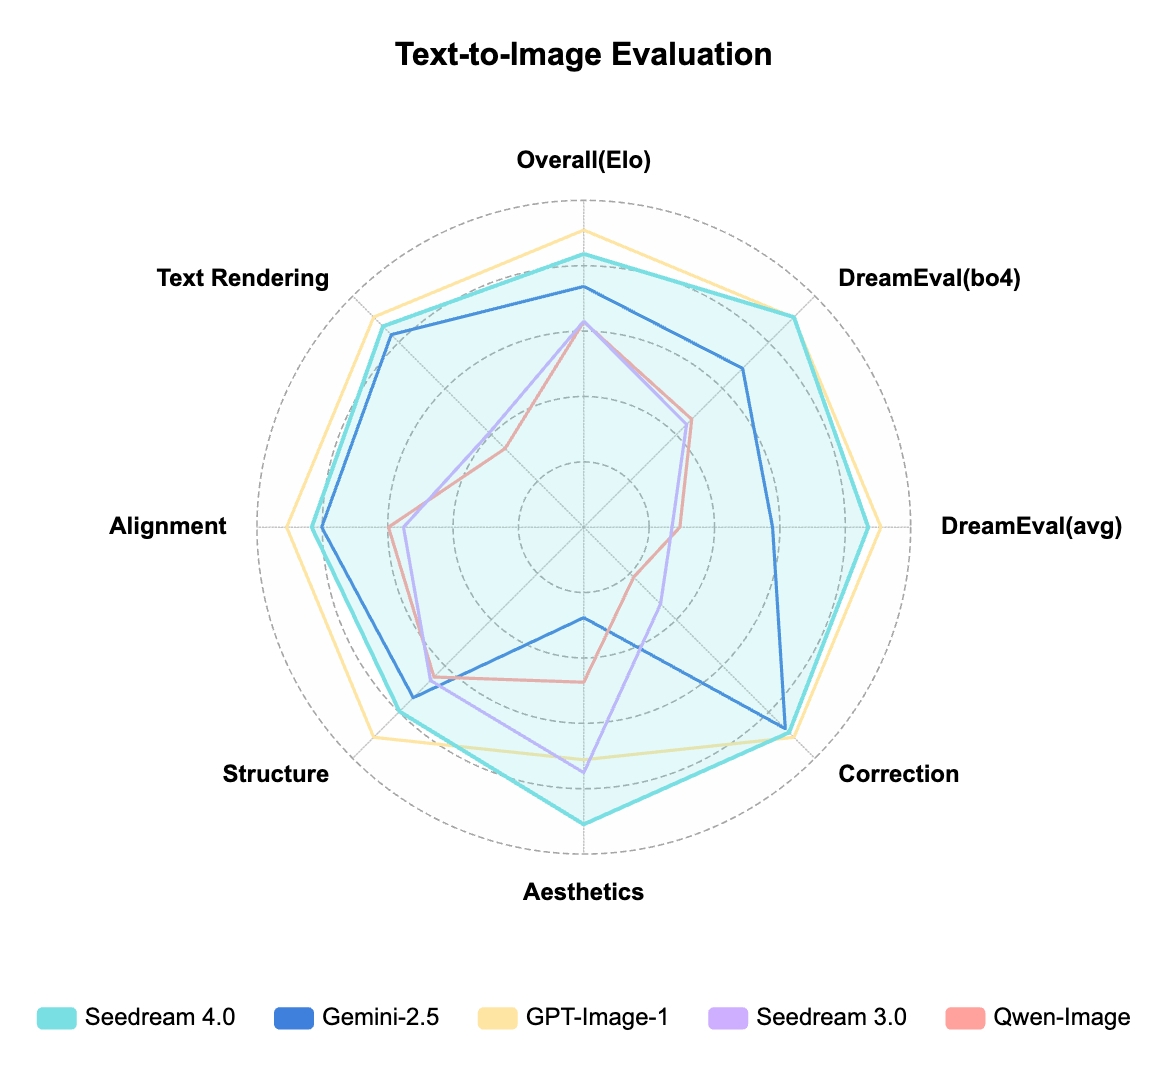
vs Gemini 2.5 Flash Image: Seedream 4 demonstrates superior understanding of user intent, producing more accurate and contextually relevant edits. It also outperforms Gemini 2.5 in maintaining character consistency and complex scene detail.
vs Seedream 3.0: Seedream 4 achieves about 35% faster inference speeds and supports higher output resolutions up to 4K. It also unifies generation and editing capabilities into one model, unlike Seedream 3.50 which handles these separately.
vs Flux Kontext: Seedream 4 provides significantly better prompt adherence, image alignment, and text rendering quality. Flux Kontext often produces inconsistent compositions and less polished images.
vs Qwen-Image: Seedream 4 handles complex scenes and multi-object prompts with better accuracy and coherence. Qwen-Image struggles with complex logic and retrieves weaker prompt alignment.
Measured on the AI/ML API gateway across live traffic. Figures are medians unless stated. Last updated 2026-10-12.
import requests

r = requests.post(
    "https://api.aimlapi.com/v1/images/generations",
    headers={"Authorization": "Bearer " + AIMLAPI_KEY},
    json={
      "model": "bytedance/seedream-v4-text-to-image",
      "prompt": "A cat holding a sign that says hello"
    },
)
print(r.json())
const r = await fetch("https://api.aimlapi.com/v1/images/generations", {
  method: "POST",
  headers: {
    Authorization: `Bearer ${process.env.AIMLAPI_KEY}`,
    "Content-Type": "application/json",
  },
  body: JSON.stringify({
    "model": "bytedance/seedream-v4-text-to-image",
    "prompt": "A cat holding a sign that says hello"
  }),
});
console.log(await r.json());
curl -X POST https://api.aimlapi.com/v1/images/generations \
  -H "Authorization: Bearer $AIMLAPI_KEY" \
  -H "Content-Type: application/json" \
  -d '{"model":"bytedance/seedream-v4-text-to-image","prompt":"A cat holding a sign that says hello"}'
OpenAI-compatible — swap the base URL and it works with your existing SDK.
| Type | Price |
|---|---|
| Output | |
| Model | Input | Output | Context | Best for |
|---|---|---|---|---|
Seedream 4 Text-to-Image This page | Image generation at scale | |||
| Image generation at scale | ||||
| Image generation at scale | ||||
| Image generation at scale | ||||
| Image generation at scale |
Seedream 4 Text-to-Image takes image, text as input and returns image.
Seedream 4 Text-to-Image is priced at $0.039 / gen (variable).
Seedream 4 Text-to-Image is billed per generation — a fixed charge per output rather than by prompt length.
Yes, Seedream 4 Text-to-Image accepts image input as well as a text prompt.
Seedream 4 Text-to-Image was built by ByteDance.
Send a request to https://api.aimlapi.com/v1/images/generations with bytedance/seedream-v4-text-to-image as the model id.
Yes. Seedream 4 Text-to-Image is served through AI/ML API, so the same key and endpoint format used for other models applies.