Claude Fable 5.2 vs GPT-6.1 Sol vs Opus 5.5: Our Tests
We gave Fable 5.2, GPT-6.1 Sol and Opus 5.5 two coding tasks: fix a Python file and build an animated city in a single HTML page. All three passed the Python checks and met the city prompt. Sol cost the least in both runs; Opus finished the Python fix first.
Fable 5.2, Sol and Opus: prices and specs
Anthropic released Fable 5.2 on November 9, 2026, as the successor to Fable 5.1. It accepts text and images, supports up to 128K output tokens and offers five reasoning effort levels. All three models below are available through AI/ML API with one account and API key.
Swipe to compare
| Per 1M tokens unless stated | Fable 5.2 | GPT-6.1 Sol | Opus 5.5 |
|---|---|---|---|
| Uncached input | $8 | $2 | $4 |
| Cached input | $0.20 | $0.10 | $0.20 |
| Output, including thinking | $40 | $10 | $20 |
| Context window | 1M tokens | 1.05M tokens | 1M tokens |
Sources: AI/ML API model pages for Fable 5.2, GPT-6.1 Sol and Opus 5.5, checked November 10, 2026. Cached rates apply to eligible reused input; cache writes and special long-context tiers have separate billing rules.
What our coding tests showed
We made one request per model for each task through AI/ML API on November 10, 2026, using the same prompts and reasoning_effort="high". With one run per task, we cannot estimate each model’s usual cost or success rate.
Swipe to compare
| Task | Model | Result | Time | API cost |
|---|---|---|---|---|
| Python bug fix | Fable 5.2 | 22/22 tests passed | 26 s | $0.11 |
| Python bug fix | GPT-6.1 Sol | 22/22 tests passed | 39 s | $0.02 |
| Python bug fix | Opus 5.5 | 22/22 tests passed | 17 s | $0.04 |
| Animated city page | Fable 5.2 | Prompt requirements met | 247 s | $1.05 |
| Animated city page | GPT-6.1 Sol | Prompt requirements met | 121 s | $0.08 |
| Animated city page | Opus 5.5 | Prompt requirements met | 230 s | $0.52 |
Python: all three passed 22 checks
The file contained three functions with bugs in duration parsing, input validation and interval merging. Each model passed all 22 supplied tests. Opus finished first at 17 seconds; Sol had the lowest charge at $0.02.
Animated city: Fable added detail at a higher cost
The prompt asked for one self-contained HTML file with a canvas skyline, changing window lights, cars with headlights, a moon and a working day/night button. All three pages met those requirements. Fable drew three rows of buildings and four lanes of traffic; Sol used two lanes with evenly spaced cars. Opus also produced a working scene.
Fable’s city request cost $1.05, compared with $0.52 for Opus and $0.08 for Sol. All three pages included the requested features.
Read the exact city prompt
Write a single self-contained HTML file (no external libraries, no network requests) that shows an animated night city on a canvas that fills the window. It needs a skyline of buildings with lit windows that slowly turn on and off, a road with at least five cars driving in both directions with headlights on, a moon, and a button in the top-left corner that switches the scene between night and day. Return only the HTML in one code block.Watch the longer demos and see their costs
These longer demonstrations use different workloads and settings from our two single-request tasks. Their costs do not belong in the test table above.
Cars voxel scene: Fable vs Sol
The separate Piston Cup demo reports $108.87 for Fable 5.2 and $13.02 for GPT-6.1 Sol. The video shows the generated scenes:
Glass pool: a creator’s Fable vs Opus comparison
Mr Tactical’s comparison reports 90 minutes and $57.87 for Fable, versus 68 minutes and $14.39 for Opus. He preferred Fable’s sunset and night scenes. That is his visual assessment of a separate workflow.
Fable 5.2 vs Sol and Opus: benchmarks
Artificial Analysis’s Intelligence Index combines results from its evaluation tasks. At high effort, Fable scores 62, Opus 52 and Sol 50. These are external benchmark results, separate from our coding requests. The same effort name does not mean the providers used the same compute budget.
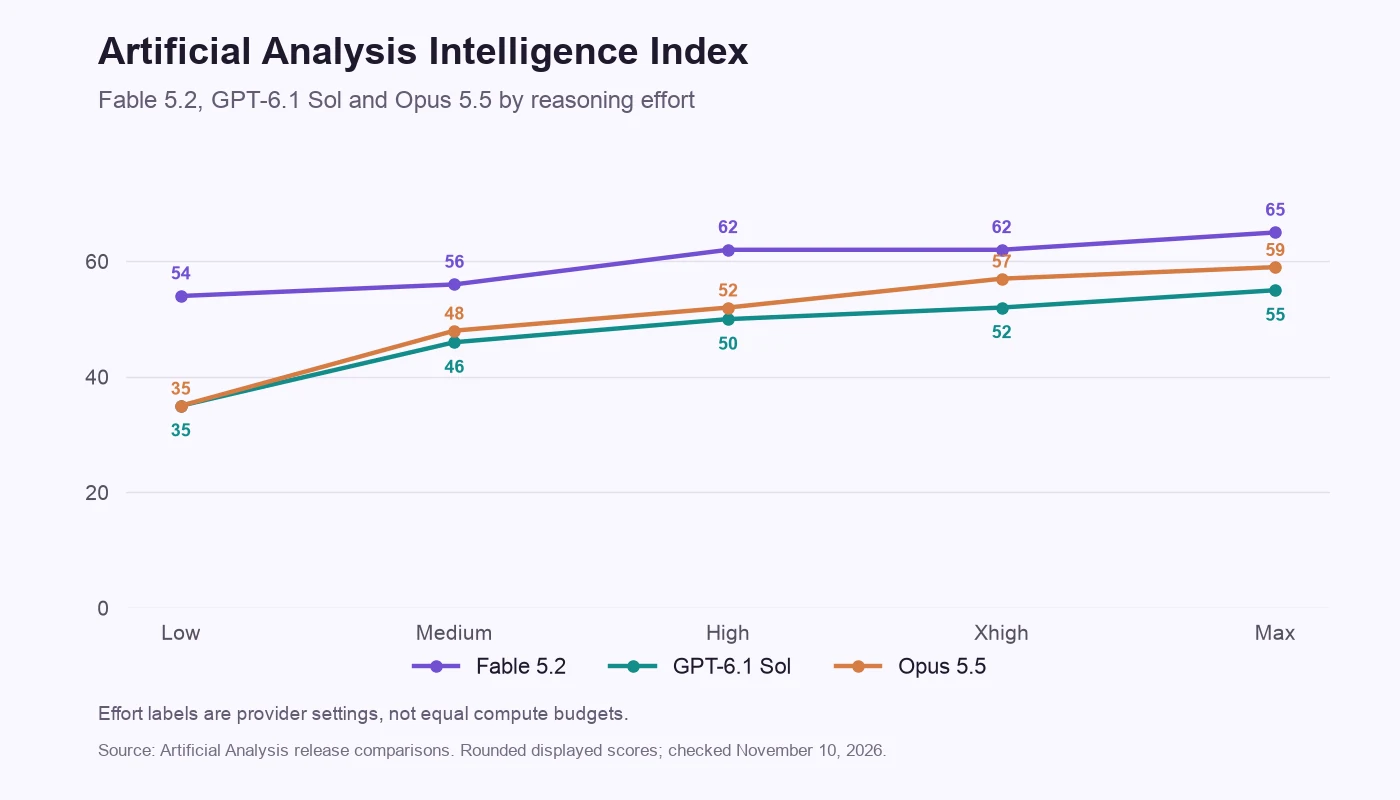
Sol at max scores 55, between Fable at low (54) and medium (56). Opus at max scores 59, below Fable at high (62). See the Fable vs Sol and Fable vs Opus comparison pages for the settings.
AA cost and time at high effort
These cost and time metrics describe Artificial Analysis’s evaluation workload. They are not our AI/ML API charges or a forecast for your prompts.
| Model | Intelligence Index | AA Cost per Task | AA Time per Task |
|---|---|---|---|
| Claude Fable 5.2 | 62 | $9.08 | 17.4 min |
| GPT-6.1 Sol | 50 | $0.59 | 6.5 min |
| Claude Opus 5.5 | 52 | $3.46 | 9.5 min |
Six Anthropic benchmarks: Fable 5.2 vs Opus 5.5
These six rows come from Anthropic’s launch table. The models use their highest available effort unless marked otherwise. Fable leads on these rows; Opus remains ahead on AA-Briefcase Elo, 1800 against 1785. Elo is a different measure from the rubric score shown alongside it.
| Benchmark | What it measures | Fable 5.2 | Opus 5.5 |
|---|---|---|---|
| FrontierCode 2.0 | Changes maintainers would merge | 49.1% (xhigh) | 45.5% |
| FrontierSWE v2 | Agentic coding | 69.9% | 62.3% |
| AutomationBench | Business workflows | 51.4% | 42.5% |
| WANDR, relaxed score | Large data-collection tasks | 82.1% | 72.3% |
| OSWorld 2.1 | Computer use, offline set | 89.3% | 87.2% |
| Humanity’s Last Exam, with tools | Expert reasoning across subjects | 74.2% | 67.7% |
In Anthropic’s FrontierCode comparison, Fable at high effort scored 45.3%, close to Opus at max effort at 45.5%, for roughly half the cost per task. Anthropic used different effort settings for the two models.
Choosing between Sol, Opus and Fable
GPT-6.1 Sol
We would start with Sol for tasks like our Python fix and city page. It met both prompts at the lowest cost.
Claude Opus 5.5
Anthropic recommends Opus for most coding and knowledge work. It costs half as much as Fable per standard input and output token. In our Python run, it finished in 17 seconds, against Fable’s 26 and Sol’s 39. Sol still cost less for that request.
Claude Fable 5.2
Try Fable on a prompt Sol or Opus fails. It leads the three on the Intelligence Index at high effort, and Anthropic reports higher Fable scores on the six benchmarks above. Our two prompts showed no difference in whether the models met the requirements, while Fable cost the most.
How to compare them through AI/ML API
- Create your API key. Sign up, add funds to your balance and create a key on the API keys page.
- Try the same prompt. You can compare Fable and Opus in Playground. Keep the prompt and effort setting unchanged when switching models.
- Record the result and charge. Check whether each response meets your requirements, then compare time, usage and the cost of any retries.
Python example and model IDs
Install the openai package and set AIMLAPI_KEY in your environment. This example uses the OpenAI-compatible chat endpoint:
import os
from openai import OpenAI

client = OpenAI(
    base_url="https://api.aimlapi.com/v1",
    api_key=os.environ["AIMLAPI_KEY"],
)

response = client.chat.completions.create(
    model="anthropic/claude-fable-5-2",
    reasoning_effort="high",
    max_tokens=32000,
    messages=[{
        "role": "user",
        "content": "Find and fix the bugs in this function: ...",
    }],
)

print(response.choices[0].message.content)
print(response.usage)
Use anthropic/claude-opus-5-5 or openai/gpt-6.1-sol to compare the other models. The output limit also covers reasoning, so the visible answer may be shorter than 32,000 tokens. See the Fable request settings for route-specific options.
Frequently asked questions
What changed from Fable 5.1?
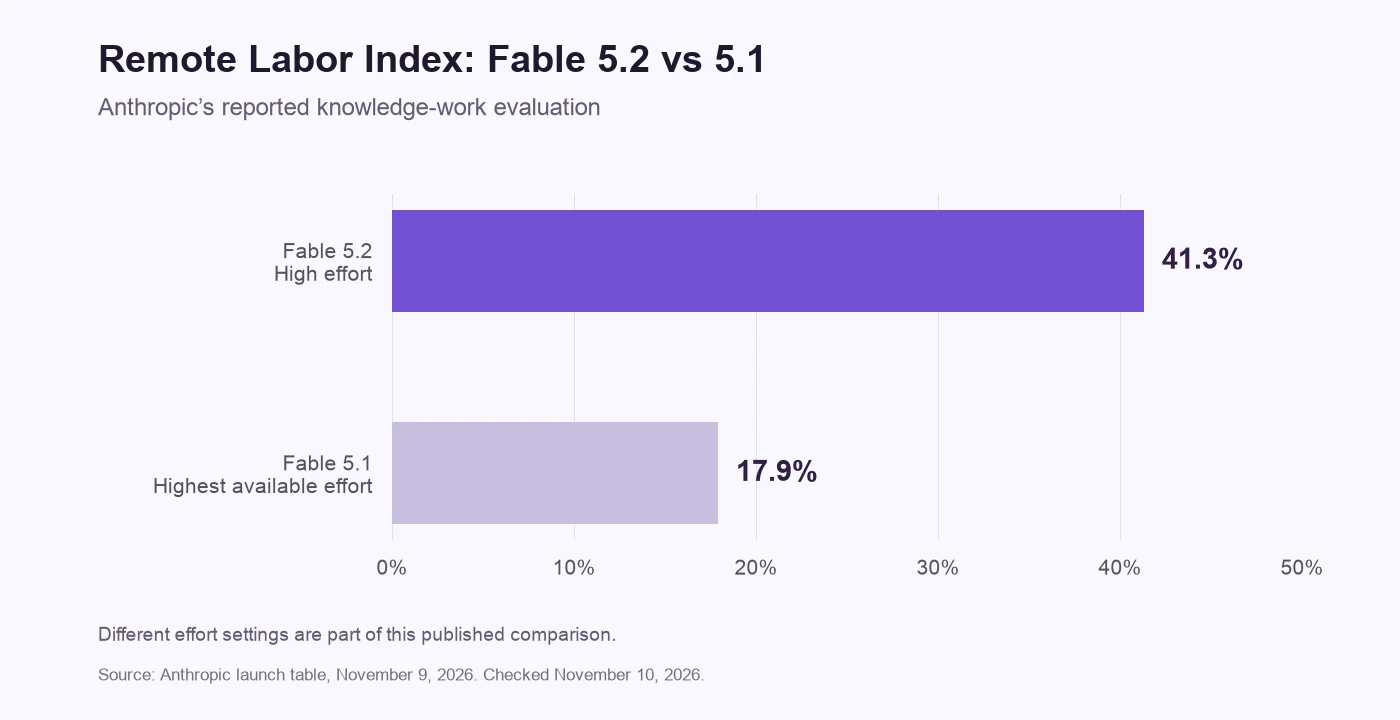
Anthropic reports output generation up to 30% faster than Fable 5.1 and lower token prices. It also reports a FrontierSWE v2 improvement from 56.3% to 69.9%. On Remote Labor Index, Fable 5.2 scored 41.3% at high effort, versus 17.9% for Fable 5.1 at its highest effort. The settings differ in that comparison. Published results.
Are Fable 5.2 and Mythos 5.2 the same model?
Anthropic describes them as the same underlying model at the same base price. Fable has safeguards that allow public availability; Mythos is limited to vetted organizations in Anthropic’s verification programs. This guide covers the Fable route offered by AI/ML API. Anthropic’s explanation.
Is Fable 5.2 free?
No. API usage is billed. Our two Fable requests cost $1.16 together: $0.11 for Python and $1.05 for the city. Other prompts and effort settings can produce different charges.