GPT-6.2 Astra vs Claude Fable 5.2: Release & Pricing
OpenAI released GPT-6.2 Astra on November 17, 2026, as the successor to GPT-6 Astra. The new flagship targets difficult coding and professional work, with lower API prices than its predecessor. You can use it through AI/ML API alongside Claude Fable 5.2, Anthropic's current model for demanding technical tasks. OpenAI's announcement, Claude Fable.
Astra and Fable now have the same standard input and output token prices. The useful question is how much each model spends to finish work you can accept. In the evaluated configurations compared here, Fable scores higher on the independent Intelligence Index, while Astra leads selected professional and agent evaluations. Artificial Analysis records lower evaluated task cost and time for Astra.
This guide explains the release, the benchmark exceptions and the billing conditions, then shows how to call Astra through AI/ML API. Our Python and animated-city checks add two outputs you can inspect before trying the models on your own work.
What is GPT-6.2 Astra?
GPT-6.2 Astra is the flagship of OpenAI's two-model GPT-6.2 release. Sol is the lower-cost model in the same family. Astra accepts text and images and returns text, so a request can combine a written specification with a screenshot or document image. Astra model documentation.
These are the main limits documented for Astra:
| Specification | GPT-6.2 Astra |
|---|---|
| Direct API model ID | gpt-6.2-astra |
| AI/ML API model ID | openai/gpt-6.2-astra |
| Context window | 1,050,000 tokens |
| Maximum input | 922,000 tokens |
| Maximum output | 128,000 tokens |
| Input and output | Text/images in; text out |
| Knowledge cutoff | May 18, 2026 |
The context window covers the material available during a request, including room for the response. The separate input ceiling determines how much you can submit. For a repository review, budget for instructions and conversation history alongside the files; a 1.05-million-token context does not permit a prompt of that size.
Fable 5.2 has a one-million-token context and a 128,000-token output limit. Both therefore accommodate large inputs, although the billing rules differ once an Astra prompt exceeds 272,000 tokens. Long-context capacity helps you supply relevant material together; it does not establish how accurately a model will use every passage. Fable model overview.
What's new in GPT-6.2 Astra?
Professional work with a finished deliverable
OpenAI reports improved professional outputs, including closer adherence to field conventions and supplied templates. On its internal GDPvalv2 evaluation, Astra gains 6.2 percentage points over GPT-6 Astra while using 22% fewer output tokens. Those are provider measurements of that workload. GPT-6.2 release results.
For a financial workbook or client document, correctness includes the form of the deliverable. A calculation can be right while the workbook is difficult to audit; a draft can contain the requested information while ignoring the supplied template. Give Astra the actual template and acceptance criteria when you evaluate the upgrade. Then check whether the result needs less manual restructuring. That is a more useful migration test than asking both versions for an unconstrained summary.
Coding instructions and long workflows
OpenAI also reports cleaner code and improved interactive frontends in Astra 6.2. For an existing project, inspect whether generated changes follow its conventions and whether the resulting interface behaves as specified. GPT-6.2 release.
OpenAI's current Astra prompting guidance recommends supplying project conventions for coding and explicit visual direction for frontend work. It also describes a more concise default writing style. Review old prompts that repeatedly demand brevity: those instructions can remove explanations you still need, such as the reason for a migration or a record of failed checks.
OpenAI's integration guidance calls the earlier messages and tool results carried into the next request the conversation prefix. Changing that history can discard reasoning retained from earlier turns, so the model may repeat work. An agent that edits an old instruction or shortens an earlier tool result between turns can trigger this behavior. Rewriting the beginning of a conversation can also reduce cache eligibility. Append corrections or new instructions where possible instead of rewriting earlier messages. Conversation-prefix guidance.
GPT-6.2 Astra vs Claude Fable 5.2: benchmarks
OpenAI's launch comparison
The following results come from OpenAI's launch charts. Both columns use the published max-effort configuration. Higher is better in every row.
FrontierCode checks whether a code change is ready for a maintainer to merge. Agents' Last Exam tests multistep professional work, while GDPvalv2 Internal covers extended knowledge-work assignments. Harvey LAB-AA tests source-grounded legal deliverables. FrontierCode methodology, Harvey methodology.
| Evaluation | GPT-6.2 Astra | Claude Fable 5.2 |
|---|---|---|
| FrontierCode 2.0 | 44.2% | 45.6% |
| Agents' Last Exam v1.1 | 77.6% | 72.8% |
| GDPvalv2 Internal | 50.4% | 44.8% |
| Harvey LAB-AA v1.1, hallucination-gated all-pass | 15.0% | 7.2% |
Astra leads the selected agent and professional-work evaluations, while Fable has the higher FrontierCode score. For a repository agent, keep that coding result separate from the deliverable scores: an auditable workbook and an accepted code change test different skills.
Fable's Agents' Last Exam result excludes nine tasks that used a fallback model. GDPvalv2 Internal is OpenAI's evaluation and differs from Artificial Analysis's GDPval-AA. Harvey counts an assignment as successful only when it passes every criterion without a material hallucination. Its all-pass percentage uses a different scoring rule from the other rows.
Artificial Analysis's independent comparison
Artificial Analysis provides a broader comparison and records the resources used by its evaluated configurations. Its Fable entry is explicitly labeled “Max, Default Fallback”; Astra uses max effort.
| Artificial Analysis metric | GPT-6.2 Astra | Claude Fable 5.2 |
|---|---|---|
| Intelligence Index v5.0.1 | 62 | 65 |
| Cost per Intelligence Index task | $4.00 | $26.54 |
| Time per Intelligence Index task | 10.4 minutes | 40.8 minutes |
Fable earns the higher aggregate score, while Astra uses less money and time on this benchmark workload. The index combines evaluations, so its ordering can differ from a single professional-work or coding result. These tables show that difference; they do not identify its cause.
AA's cost is a weighted calculation that includes input, caching and reasoning or answer tokens. Its task time includes the wait for a completed answer. Use these figures to decide which model deserves a trial under your deadline and budget, then measure your actual task. They are separate from both standard token rates and the subscription-based checks below.
GPT-6.2 Astra pricing
Astra's standard input and output prices are 20% below GPT-6 Astra's; cached input is 60% lower. The current AI/ML API chat-completions cards match the standard vendor rates below, checked on November 18, 2026. Prices are US dollars per million tokens. Astra pricing, Claude pricing, AI/ML API model catalog.
| Model | Uncached input | Cache read | Output |
|---|---|---|---|
| GPT-6.2 Astra | $8 | $0.40 | $40 |
| Claude Fable 5.2 | $8 | $0.20 | $40 |
At these rates, 100,000 uncached input tokens and 10,000 billable output tokens cost $1.20 with either model. Equal token counts produce the same bill in that example. In practice, reasoning contributes to output usage, so the visible answer alone cannot tell you how much the request cost.
For Astra, an input above 272,000 tokens raises rates for the whole request: input and cache reads double, while output costs 1.5 times the standard rate. A request with 300,000 uncached input tokens and 10,000 billable output tokens therefore costs $5.40. Fable's standard rates cover its full context, making the same counts $2.80. Sending a large repository can consequently change the price comparison even before either model starts reasoning.
Fable also has the lower cache-read price. That can help a repeated workflow with an eligible shared prefix, but cache writes have their own charges and a changed prefix may miss the cache. Compare the usage recorded for your sequence of requests rather than assuming every repeated token receives the read rate.
The independent evaluation illustrates the other side of this calculation: Astra's matched standard rates did not produce a matched benchmark bill. Start with the settings your application will use, keep the same acceptance checks and total the charge across attempts. A cheaper first response is useful only if it reaches the required result.
How did GPT-6.2 Astra do in our coding tests?
We asked Astra and Fable for two deliverables in one combined request: a Python module with strict validation rules and a self-contained animated city. The first gives us executable checks; the second lets you inspect how the model turns a short visual specification into a working page.
Both ran at high effort without tools or repair turns. Astra used Codex CLI on November 17; Fable used the Claude web interface on November 18, Moscow time. These were subscription runs through different clients. We have no comparable API bill or request-time measurement for them, and a shared effort label does not establish equal compute.
Python duration parsing and interval merging
The module needed to parse durations such as 1h30m, reject malformed values and merge touching intervals without changing the input. Edge cases included booleans passed as numbers, nonfinite endpoints and out-of-order duration units. Those details are easy to miss when an implementation only handles the examples in the prompt.
Both modules passed all 61 checks. They accepted valid inputs, rejected the invalid cases in our suite and left the caller's interval data unchanged. You can inspect the Astra module and Fable module. The result gives us no correctness distinction on these cases; a harder repository task would need its own tests.
Python test details and full logs
The same frozen runner checked both modules. These counts come from the saved reports for the original runs.
| Check group | GPT-6.2 Astra | Claude Fable 5.2 |
|---|---|---|
| Valid duration inputs | 12/12 | 12/12 |
| Rejected duration inputs | 20/20 | 20/20 |
| Interval results and unchanged input | 12/12 | 12/12 |
| Rejected interval inputs | 17/17 | 17/17 |
| Total | 61/61 | 61/61 |
Each valid interval case also checks that the function returns a new list of tuples and leaves the input unchanged. An invalid-input pass means the runner caught the required ValueError.
Selected cases from those reports:
| Input | GPT-6.2 Astra | Claude Fable 5.2 |
|---|---|---|
parse_duration("1h30m") |
5400 |
5400 |
parse_duration(" 1H 2M 3S ") |
3723 |
3723 |
parse_duration("1s1m") |
ValueError |
ValueError |
merge_intervals([[3,5],[1,3],[8,8]]) |
[(1, 5), (8, 8)] |
[(1, 5), (8, 8)] |
merge_intervals([[True,2]]) |
ValueError |
ValueError |
merge_intervals([[0,float("inf")]]) |
ValueError |
ValueError |
GPT-6.2 Astra full log (JSON) · Claude Fable 5.2 full log (JSON) · Frozen test runner.
Download the runner and one module, save them in the same folder, then run:
python3 test_runner.py candidate.py
The runner prints the case-by-case JSON report and applies an eight-second execution timeout.
GPT-6.2 Astra: original Python module
import math
import re


_DURATION = re.compile(
    r"(?:(?P<h>[0-9]+)[hH]\s*)?"
    r"(?:(?P<m>[0-9]+)[mM]\s*)?"
    r"(?:(?P<s>[0-9]+)[sS])?"
)


def parse_duration(value):
    if not isinstance(value, str):
        raise ValueError("expected a duration string")
    match = _DURATION.fullmatch(value.strip())
    if match is None or match.lastgroup is None:
        raise ValueError("invalid duration")

    total = 0
    for digits, scale in zip(match.groups(), (3600, 60, 1)):
        if digits is not None:
            number = 0
            for digit in digits:
                number = number * 10 + ord(digit) - 48
            total += number * scale
    return total


def merge_intervals(intervals):
    if not isinstance(intervals, list):
        raise ValueError("expected a list")
    ordered = []
    for pair in intervals:
        if not isinstance(pair, (list, tuple)) or len(pair) != 2:
            raise ValueError("expected a pair")
        start, end = pair
        for x in pair:
            if isinstance(x, bool) or not isinstance(x, (int, float)):
                raise ValueError("expected numeric endpoint")
            if isinstance(x, float) and not math.isfinite(x):
                raise ValueError("expected finite endpoint")
        if start > end:
            raise ValueError("reversed interval")
        ordered.append((start, end))

    merged = []
    for start, end in sorted(ordered):
        if merged and start <= merged[-1][1]:
            left, right = merged[-1]
            merged[-1] = (left, max(right, end))
        else:
            merged.append((start, end))
    return merged
GPT-6.2 Astra: full recorded test log
{
  "passed": 61,
  "total": 61,
  "cases": [
    {
      "case": "parse_valid_0",
      "passed": true,
      "detail": "3600"
    },
    {
      "case": "parse_valid_1",
      "passed": true,
      "detail": "5400"
    },
    {
      "case": "parse_valid_2",
      "passed": true,
      "detail": "125"
    },
    {
      "case": "parse_valid_3",
      "passed": true,
      "detail": "0"
    },
    {
      "case": "parse_valid_4",
      "passed": true,
      "detail": "3723"
    },
    {
      "case": "parse_valid_5",
      "passed": true,
      "detail": "5400"
    },
    {
      "case": "parse_valid_6",
      "passed": true,
      "detail": "120"
    },
    {
      "case": "parse_valid_7",
      "passed": true,
      "detail": "3723"
    },
    {
      "case": "parse_valid_8",
      "passed": true,
      "detail": "7200"
    },
    {
      "case": "parse_valid_9",
      "passed": true,
      "detail": "11040"
    },
    {
      "case": "parse_valid_10",
      "passed": true,
      "detail": "62"
    },
    {
      "case": "parse_valid_11",
      "passed": true,
      "detail": "2"
    },
    {
      "case": "parse_invalid_0",
      "passed": true
    },
    {
      "case": "parse_invalid_1",
      "passed": true
    },
    {
      "case": "parse_invalid_2",
      "passed": true
    },
    {
      "case": "parse_invalid_3",
      "passed": true
    },
    {
      "case": "parse_invalid_4",
      "passed": true
    },
    {
      "case": "parse_invalid_5",
      "passed": true
    },
    {
      "case": "parse_invalid_6",
      "passed": true
    },
    {
      "case": "parse_invalid_7",
      "passed": true
    },
    {
      "case": "parse_invalid_8",
      "passed": true
    },
    {
      "case": "parse_invalid_9",
      "passed": true
    },
    {
      "case": "parse_invalid_10",
      "passed": true
    },
    {
      "case": "parse_invalid_11",
      "passed": true
    },
    {
      "case": "parse_invalid_12",
      "passed": true
    },
    {
      "case": "parse_invalid_13",
      "passed": true
    },
    {
      "case": "parse_invalid_14",
      "passed": true
    },
    {
      "case": "parse_invalid_15",
      "passed": true
    },
    {
      "case": "parse_invalid_16",
      "passed": true
    },
    {
      "case": "parse_invalid_17",
      "passed": true
    },
    {
      "case": "parse_invalid_18",
      "passed": true
    },
    {
      "case": "parse_invalid_19",
      "passed": true
    },
    {
      "case": "merge_valid_nonmutation_0",
      "passed": true,
      "detail": "[]"
    },
    {
      "case": "merge_valid_nonmutation_1",
      "passed": true,
      "detail": "[(1, 5), (8, 8)]"
    },
    {
      "case": "merge_valid_nonmutation_2",
      "passed": true,
      "detail": "[(1, 2), (5, 6)]"
    },
    {
      "case": "merge_valid_nonmutation_3",
      "passed": true,
      "detail": "[(1, 10)]"
    },
    {
      "case": "merge_valid_nonmutation_4",
      "passed": true,
      "detail": "[(1, 2)]"
    },
    {
      "case": "merge_valid_nonmutation_5",
      "passed": true,
      "detail": "[(0, 1)]"
    },
    {
      "case": "merge_valid_nonmutation_6",
      "passed": true,
      "detail": "[(-4, 0)]"
    },
    {
      "case": "merge_valid_nonmutation_7",
      "passed": true,
      "detail": "[(1.5, 3.5)]"
    },
    {
      "case": "merge_valid_nonmutation_8",
      "passed": true,
      "detail": "[(1, 5)]"
    },
    {
      "case": "merge_valid_nonmutation_9",
      "passed": true,
      "detail": "[(7, 7)]"
    },
    {
      "case": "merge_valid_nonmutation_10",
      "passed": true,
      "detail": "[(1, 4), (6, 7), (9, 10)]"
    },
    {
      "case": "merge_valid_nonmutation_11",
      "passed": true,
      "detail": "[(0, 1), (1.0001, 2)]"
    },
    {
      "case": "merge_invalid_0",
      "passed": true
    },
    {
      "case": "merge_invalid_1",
      "passed": true
    },
    {
      "case": "merge_invalid_2",
      "passed": true
    },
    {
      "case": "merge_invalid_3",
      "passed": true
    },
    {
      "case": "merge_invalid_4",
      "passed": true
    },
    {
      "case": "merge_invalid_5",
      "passed": true
    },
    {
      "case": "merge_invalid_6",
      "passed": true
    },
    {
      "case": "merge_invalid_7",
      "passed": true
    },
    {
      "case": "merge_invalid_8",
      "passed": true
    },
    {
      "case": "merge_invalid_9",
      "passed": true
    },
    {
      "case": "merge_invalid_10",
      "passed": true
    },
    {
      "case": "merge_invalid_11",
      "passed": true
    },
    {
      "case": "merge_invalid_12",
      "passed": true
    },
    {
      "case": "merge_invalid_13",
      "passed": true
    },
    {
      "case": "merge_invalid_14",
      "passed": true
    },
    {
      "case": "merge_invalid_15",
      "passed": true
    },
    {
      "case": "merge_invalid_16",
      "passed": true
    }
  ],
  "harness_sha256": "09f0bb2751cc62d5947e85b3e1293d0fa480e46011be7c782c961e49dbded563"
}
Claude Fable 5.2: original Python module
import math
import re

_DURATION = re.compile(r"(?:([0-9]+)[hH]\s*)?(?:([0-9]+)[mM]\s*)?(?:([0-9]+)[sS])?")


def parse_duration(value):
    """Parse strings like '1h30m' or '2m 5s' into total integer seconds."""
    if not isinstance(value, str):
        raise ValueError("duration must be a string")
    text = value.strip()
    match = _DURATION.fullmatch(text)
    if not text or match is None:
        raise ValueError(f"invalid duration: {value!r}")
    hours, minutes, seconds = (int(g) if g else 0 for g in match.groups())
    return hours * 3600 + minutes * 60 + seconds


def _check_endpoint(x):
    if isinstance(x, bool) or not isinstance(x, (int, float)):
        raise ValueError(f"invalid endpoint: {x!r}")
    if isinstance(x, float) and not math.isfinite(x):
        raise ValueError(f"non-finite endpoint: {x!r}")


def merge_intervals(intervals):
    """Return sorted tuples with overlapping or touching intervals merged."""
    if not isinstance(intervals, list):
        raise ValueError("intervals must be a list")
    items = []
    for pair in intervals:
        if not isinstance(pair, (list, tuple)) or len(pair) != 2:
            raise ValueError(f"invalid pair: {pair!r}")
        start, end = pair
        _check_endpoint(start)
        _check_endpoint(end)
        if start > end:
            raise ValueError(f"reversed interval: {pair!r}")
        items.append((start, end))
    items.sort(key=lambda p: p[0])
    merged = []
    for start, end in items:
        if merged and start <= merged[-1][1]:
            if end > merged[-1][1]:
                merged[-1] = (merged[-1][0], end)
        else:
            merged.append((start, end))
    return merged
Claude Fable 5.2: full recorded test log
{
  "passed": 61,
  "total": 61,
  "cases": [
    {
      "case": "parse_valid_0",
      "passed": true,
      "detail": "3600"
    },
    {
      "case": "parse_valid_1",
      "passed": true,
      "detail": "5400"
    },
    {
      "case": "parse_valid_2",
      "passed": true,
      "detail": "125"
    },
    {
      "case": "parse_valid_3",
      "passed": true,
      "detail": "0"
    },
    {
      "case": "parse_valid_4",
      "passed": true,
      "detail": "3723"
    },
    {
      "case": "parse_valid_5",
      "passed": true,
      "detail": "5400"
    },
    {
      "case": "parse_valid_6",
      "passed": true,
      "detail": "120"
    },
    {
      "case": "parse_valid_7",
      "passed": true,
      "detail": "3723"
    },
    {
      "case": "parse_valid_8",
      "passed": true,
      "detail": "7200"
    },
    {
      "case": "parse_valid_9",
      "passed": true,
      "detail": "11040"
    },
    {
      "case": "parse_valid_10",
      "passed": true,
      "detail": "62"
    },
    {
      "case": "parse_valid_11",
      "passed": true,
      "detail": "2"
    },
    {
      "case": "parse_invalid_0",
      "passed": true
    },
    {
      "case": "parse_invalid_1",
      "passed": true
    },
    {
      "case": "parse_invalid_2",
      "passed": true
    },
    {
      "case": "parse_invalid_3",
      "passed": true
    },
    {
      "case": "parse_invalid_4",
      "passed": true
    },
    {
      "case": "parse_invalid_5",
      "passed": true
    },
    {
      "case": "parse_invalid_6",
      "passed": true
    },
    {
      "case": "parse_invalid_7",
      "passed": true
    },
    {
      "case": "parse_invalid_8",
      "passed": true
    },
    {
      "case": "parse_invalid_9",
      "passed": true
    },
    {
      "case": "parse_invalid_10",
      "passed": true
    },
    {
      "case": "parse_invalid_11",
      "passed": true
    },
    {
      "case": "parse_invalid_12",
      "passed": true
    },
    {
      "case": "parse_invalid_13",
      "passed": true
    },
    {
      "case": "parse_invalid_14",
      "passed": true
    },
    {
      "case": "parse_invalid_15",
      "passed": true
    },
    {
      "case": "parse_invalid_16",
      "passed": true
    },
    {
      "case": "parse_invalid_17",
      "passed": true
    },
    {
      "case": "parse_invalid_18",
      "passed": true
    },
    {
      "case": "parse_invalid_19",
      "passed": true
    },
    {
      "case": "merge_valid_nonmutation_0",
      "passed": true,
      "detail": "[]"
    },
    {
      "case": "merge_valid_nonmutation_1",
      "passed": true,
      "detail": "[(1, 5), (8, 8)]"
    },
    {
      "case": "merge_valid_nonmutation_2",
      "passed": true,
      "detail": "[(1, 2), (5, 6)]"
    },
    {
      "case": "merge_valid_nonmutation_3",
      "passed": true,
      "detail": "[(1, 10)]"
    },
    {
      "case": "merge_valid_nonmutation_4",
      "passed": true,
      "detail": "[(1, 2)]"
    },
    {
      "case": "merge_valid_nonmutation_5",
      "passed": true,
      "detail": "[(0, 1)]"
    },
    {
      "case": "merge_valid_nonmutation_6",
      "passed": true,
      "detail": "[(-4, 0)]"
    },
    {
      "case": "merge_valid_nonmutation_7",
      "passed": true,
      "detail": "[(1.5, 3.5)]"
    },
    {
      "case": "merge_valid_nonmutation_8",
      "passed": true,
      "detail": "[(1, 5)]"
    },
    {
      "case": "merge_valid_nonmutation_9",
      "passed": true,
      "detail": "[(7, 7)]"
    },
    {
      "case": "merge_valid_nonmutation_10",
      "passed": true,
      "detail": "[(1, 4), (6, 7), (9, 10)]"
    },
    {
      "case": "merge_valid_nonmutation_11",
      "passed": true,
      "detail": "[(0, 1), (1.0001, 2)]"
    },
    {
      "case": "merge_invalid_0",
      "passed": true
    },
    {
      "case": "merge_invalid_1",
      "passed": true
    },
    {
      "case": "merge_invalid_2",
      "passed": true
    },
    {
      "case": "merge_invalid_3",
      "passed": true
    },
    {
      "case": "merge_invalid_4",
      "passed": true
    },
    {
      "case": "merge_invalid_5",
      "passed": true
    },
    {
      "case": "merge_invalid_6",
      "passed": true
    },
    {
      "case": "merge_invalid_7",
      "passed": true
    },
    {
      "case": "merge_invalid_8",
      "passed": true
    },
    {
      "case": "merge_invalid_9",
      "passed": true
    },
    {
      "case": "merge_invalid_10",
      "passed": true
    },
    {
      "case": "merge_invalid_11",
      "passed": true
    },
    {
      "case": "merge_invalid_12",
      "passed": true
    },
    {
      "case": "merge_invalid_13",
      "passed": true
    },
    {
      "case": "merge_invalid_14",
      "passed": true
    },
    {
      "case": "merge_invalid_15",
      "passed": true
    },
    {
      "case": "merge_invalid_16",
      "passed": true
    }
  ],
  "harness_sha256": "09f0bb2751cc62d5947e85b3e1293d0fa480e46011be7c782c961e49dbded563"
}
Frozen Python test runner
#!/usr/bin/env python3
"""Frozen behavior checks. Runs model Python in a child interpreter, timeout 8s."""
import argparse
import copy
import hashlib
import importlib.util
import json
import math
import pathlib
import subprocess
import sys

PARSE_OK = [
    ('1h',3600), ('1h30m',5400), ('2m 5s',125), ('0s',0),
    (' 1H 2M 3S ',3723), ('90m',5400), ('120s',120),
    ('01h02m03s',3723), ('2h0s',7200), ('3h 4m',11040),
    ('1m\t2s',62), ('2s',2),
]
PARSE_BAD = ['', ' ', '123', '-1s', '+1s', '1.5h', '1s1m', '1m1h',
    '1h1h', '1m2m', '1s2s', '1d', '1 h', '1h nope', 'NaNs',
    None, True, 30, [], b'1s']
MERGE_OK = [
    ([], []), ([[3,5],[1,3],[8,8]],[(1,5),(8,8)]),
    ([[5,6],[1,2]],[(1,2),(5,6)]), ([[1,10],[2,3]],[(1,10)]),
    ([[1,2],[1,2]],[(1,2)]), ([[0,0],[0,1]],[(0,1)]),
    ([[-4,-2],[-2,0]], [(-4,0)]), ([[1.5,2.5],[2.5,3.5]],[(1.5,3.5)]),
    ([(1,2),(4,5),(2,4)],[(1,5)]), ([[7,7]],[(7,7)]),
    ([[9,10],[2,4],[1,3],[6,7]],[(1,4),(6,7),(9,10)]),
    ([[0,1],[1.0001,2]],[(0,1),(1.0001,2)]),
]
MERGE_BAD = [None, (), {}, 'ab', [1], [[1]], [[1,2,3]], [[2,1]],
    [[True,2]], [[0,False]], [['1',2]], [[None,2]], [[0,float('inf')]],
    [[float('-inf'),0]], [[0,float('nan')]], [{1,2}], [[0,complex(1,0)]]]

def child(module_path):
    spec = importlib.util.spec_from_file_location('candidate', module_path)
    module = importlib.util.module_from_spec(spec)
    try:
        spec.loader.exec_module(module)
    except BaseException as exc:
        return {'passed':0,'total':len(PARSE_OK)+len(PARSE_BAD)+len(MERGE_OK)+len(MERGE_BAD),'import_error':repr(exc)}
    records=[]
    def add(name, ok, detail=None):
        records.append({'case':name,'passed':bool(ok),**({'detail':detail} if detail else {})})
    for i,(value, expected) in enumerate(PARSE_OK):
        try:
            actual=module.parse_duration(value)
            add(f'parse_valid_{i}', type(actual) is int and actual==expected, repr(actual))
        except BaseException as exc: add(f'parse_valid_{i}',False,repr(exc))
    for i,value in enumerate(PARSE_BAD):
        try:
            actual=module.parse_duration(value)
            add(f'parse_invalid_{i}',False,repr(actual))
        except ValueError: add(f'parse_invalid_{i}',True)
        except BaseException as exc: add(f'parse_invalid_{i}',False,repr(exc))
    for i,(value, expected) in enumerate(MERGE_OK):
        inp=copy.deepcopy(value); before=copy.deepcopy(inp)
        try:
            actual=module.merge_intervals(inp)
            ok=type(actual) is list and all(type(p) is tuple for p in actual) and actual==expected and inp==before and actual is not inp
            add(f'merge_valid_nonmutation_{i}',ok,repr(actual))
        except BaseException as exc: add(f'merge_valid_nonmutation_{i}',False,repr(exc))
    for i,value in enumerate(MERGE_BAD):
        try:
            actual=module.merge_intervals(copy.deepcopy(value))
            add(f'merge_invalid_{i}',False,repr(actual))
        except ValueError: add(f'merge_invalid_{i}',True)
        except BaseException as exc: add(f'merge_invalid_{i}',False,repr(exc))
    return {'passed':sum(r['passed'] for r in records),'total':len(records),'cases':records}

if __name__=='__main__':
    parser=argparse.ArgumentParser(); parser.add_argument('module'); parser.add_argument('--child',action='store_true'); parser.add_argument('--output')
    args=parser.parse_args()
    if args.child:
        print(json.dumps(child(args.module)))
    else:
        try:
            result=subprocess.run([sys.executable,'-I',__file__,args.module,'--child'],capture_output=True,text=True,timeout=8)
            data=json.loads(result.stdout.strip().splitlines()[-1])
        except BaseException as exc: data={'runner_error':repr(exc)}
        data['harness_sha256']=hashlib.sha256(pathlib.Path(__file__).read_bytes()).hexdigest()
        out=json.dumps(data,indent=2)
        if args.output: pathlib.Path(args.output).write_text(out)
        print(out)
Animated city in one HTML file
Both pages filled the viewport and kept the day/night button usable after resizing. Desktop and mobile checks found no page errors or external requests. The scenes included moving traffic in both directions, headlights and changing lit windows.
Astra drew two layers of buildings with smaller cars and a plain moon. Fable used larger, brighter cars and added craters and a glow around the moon. Those are visible design differences within the same brief. Both delivered the requested interaction, so preference between the compositions is separate from passing the functional checks.
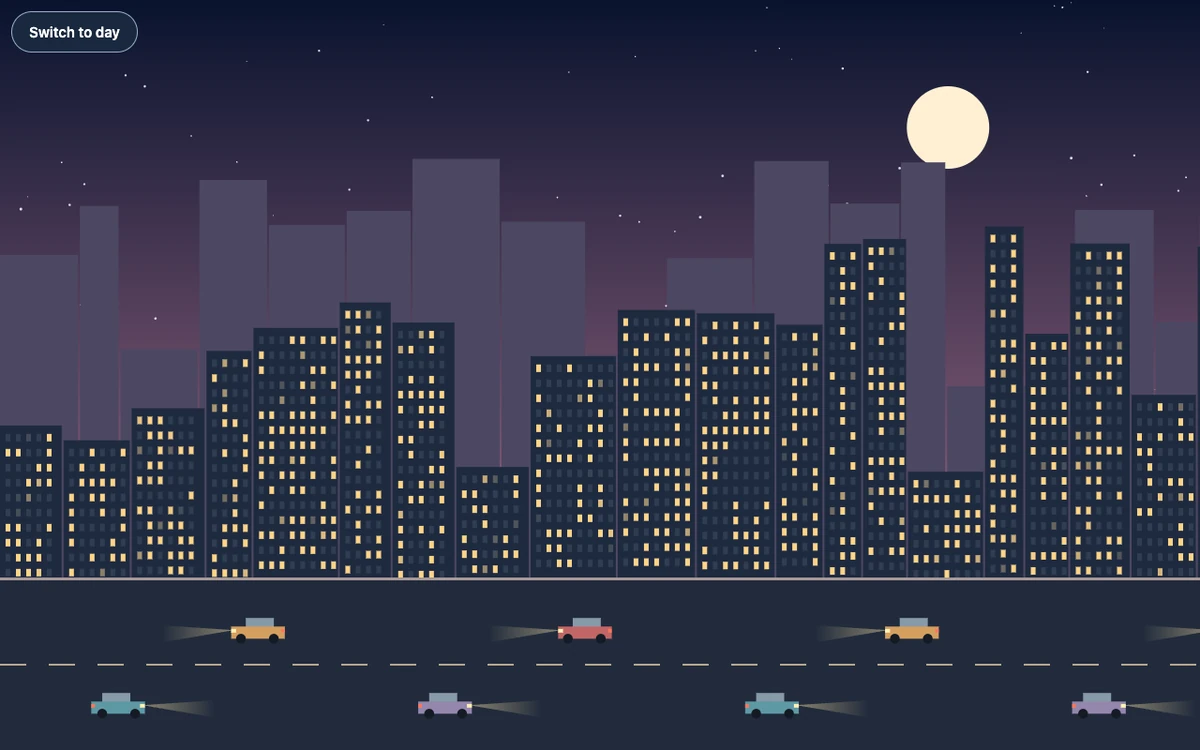
GPT-6.2 Astra. Open the interactive city.
Interactive city: GPT-6.2 Astra
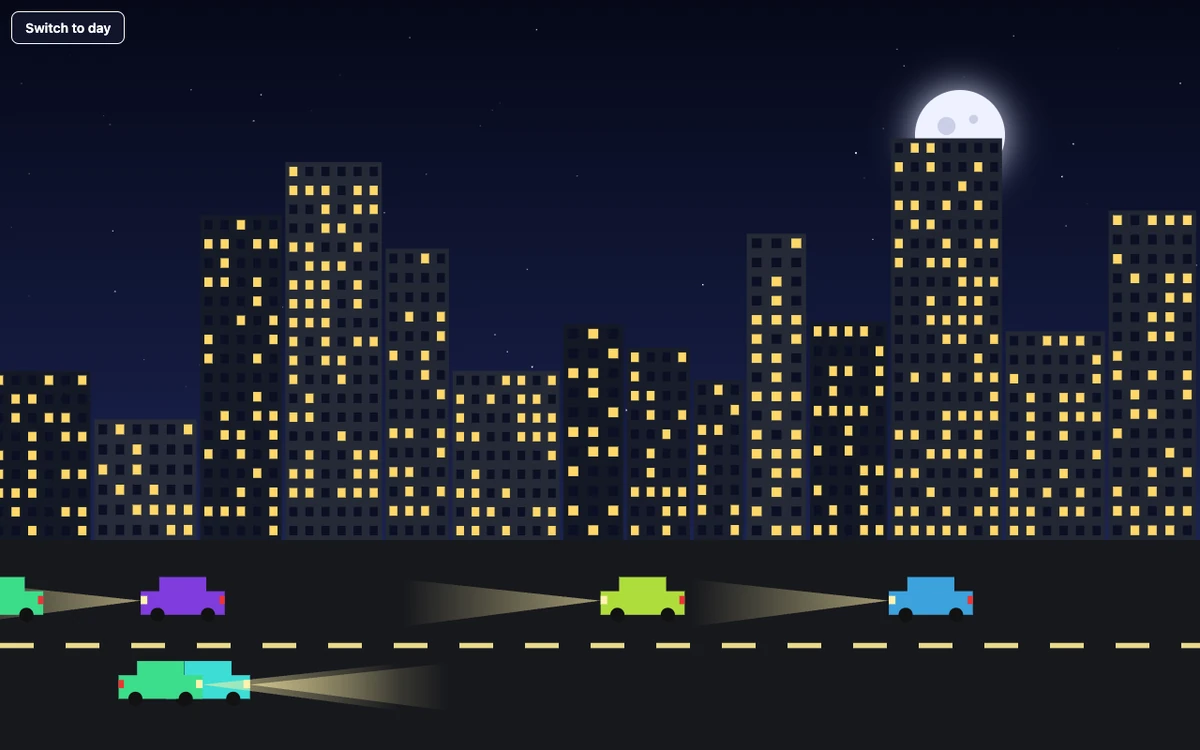
Claude Fable 5.2. Open the interactive city.
Interactive city: Claude Fable 5.2
Exact prompt used for both models
Respond directly without calling tools.

Return exactly two fenced code blocks, first python then html. No explanations. Keep the combined visible answer within about 1800 tokens. Use Python standard library only and no external resources in the HTML.

Task 1. Implement two functions in one Python module:
parse_duration(value): return total integer seconds. Accept strings containing one or more unsigned integer terms with units h, m, s, each unit at most once and in that order. Units are case-insensitive. Allow whitespace around the string and between terms, but not between a number and its unit. Examples: '1h30m', '2m 5s', '0s', ' 1H 2M 3S '. Minutes and seconds may exceed 59. Reject empty/whitespace-only values, bare numbers, signs, decimals, duplicate/out-of-order units, unknown units and non-string values, including bool. Raise ValueError for every invalid input.
merge_intervals(intervals): accept a list of pairs (each pair a list or tuple of length 2) of finite int/float endpoints; bool is invalid. Require start <= end. Return a new list of tuples sorted by start, merging overlapping or touching intervals. Do not mutate the input or its pairs. Accept zero-length and negative intervals. Empty list returns []. Invalid outer types, malformed pairs, invalid/nonfinite endpoints or reversed pairs must raise ValueError. Example: [[3,5],[1,3],[8,8]] -> [(1,5),(8,8)].

Task 2. Write one self-contained HTML file showing an animated night city on a canvas that fills the viewport and resizes with the window. Include a skyline with lit windows that slowly turn on and off, a road with at least five moving cars traveling in both directions with headlights, a moon, and a visible button at the top-left that switches between night and day. The button must remain usable after resizing. Use no external libraries, assets or network requests.
How to use GPT-6.2 Astra through AI/ML API
AI/ML API provides an OpenAI-compatible endpoint, so the Python SDK can call Astra and Fable with the same client. The model ID selects the provider. Start with a bounded task whose answer you can verify before connecting a larger workflow. AI/ML API quickstart.
Step 1: Create a key and install the SDK
Create an AI/ML API key and fund your API balance. With Python 3 installed, use these commands on macOS or Linux to store the key in your environment and install the openai package. The supported-SDK guide covers the compatible clients.
export AIMLAPI_API_KEY="your-key-here"
python3 -m pip install openai
Step 2: Send a reconciliation task
Save this example as compare_models.py. It asks Astra to reconcile invoice rows, including a duplicate and a void invoice. Integer cents keep the acceptance check exact. The example has not been executed as part of our comparison.
import json
import os
from openai import OpenAI

client = OpenAI(
    api_key=os.environ["AIMLAPI_API_KEY"],
    base_url="https://api.aimlapi.com/v1",
)

rows = [
    {"id": "INV-100", "status": "approved", "cents": 120000},
    {"id": "INV-101", "status": "approved", "cents": 45000},
    {"id": "INV-100", "status": "approved", "cents": 120000},
    {"id": "INV-102", "status": "void", "cents": 30000},
    {"id": "INV-103", "status": "approved", "cents": 80000},
]
task = (
    "Reconcile these invoice rows. Count each approved invoice ID once; "
    "exclude void invoices. Return only a JSON object with total_cents, "
    "approved_ids (sorted), and an explanation of excluded rows. Rows: "
    + json.dumps(rows)
)
response = client.chat.completions.create(
    model="openai/gpt-6.2-astra",
    messages=[{"role": "user", "content": task}],
    max_tokens=16000,
)
text = response.choices[0].message.content
print(text)
print(response.usage)
result = json.loads(text)
assert result["total_cents"] == 245000
assert result["approved_ids"] == ["INV-100", "INV-101", "INV-103"]
Run it with python3 compare_models.py. The assertions check the total and included invoices; inspect the explanation for whether the duplicate and void row were handled for the right reasons. Asking for JSON in a prompt still needs validation in the application.
Step 3: Compare Fable and inspect usage
Change the model to anthropic/claude-fable-5-2 and keep the task and checks unchanged. The example leaves reasoning controls unspecified. Use the settings documented for each model and endpoint when you tune effort; the common client does not imply a shared thinking parameter. Fable API documentation.
Read the returned usage and compare it with your account's usage logs. Record whether each response passed your checks alongside its charge.
OpenAI documents hosted search and computer-use capabilities through Responses. The example above uses the gateway's text chat endpoint. Confirm the selected route's tool support before adding those capabilities to an agent. Astra API capabilities.
Frequently asked questions
Is GPT-6.2 Astra the same model as GPT-6 Astra?
No. GPT-6.2 Astra succeeds GPT-6 Astra, with a distinct model ID and lower standard token rates.
Is GPT-6.2 Astra better than Claude Fable 5.2?
In the evaluated configurations compared here, Fable scores higher on the independent Intelligence Index and FrontierCode. Astra leads the selected professional evaluations and records lower evaluated task cost and time in AA's workload.
Can I send a million-token prompt to Astra?
Its documented maximum input is 922,000 tokens. The larger 1,050,000-token context also accommodates output, with a separate 128,000-token output ceiling. Include instructions and conversation history when estimating the input, and check the higher rates above 272,000 input tokens. Astra limits.
Can I turn off thinking or use the same settings as Fable?
Astra rejects reasoning effort none; Fable uses adaptive thinking. Follow each route's documented controls instead of copying settings between vendors. Tool availability also depends on the endpoint, so verify it separately from the model name. Astra documentation, Fable overview.
Does my ChatGPT or Claude subscription include AI/ML API usage?
No. AI/ML API requests use your AI/ML API key and balance, with billing separate from a ChatGPT or Claude subscription. AI/ML API setup.
Which model should you use?
If you already use GPT-6 Astra, start by evaluating 6.2 on the professional deliverables you repeat most often. The lower rates make the upgrade worth checking, and the release results give you specific places to look for improvement. Keep your current acceptance criteria so a shorter output does not receive credit simply for using fewer tokens.
For a new Astra/Fable integration, Astra is a reasonable first trial when evaluated task cost and completion time are priorities. Include Fable in the comparison for repository coding, where it has the higher FrontierCode score, or when Astra misses a requirement of your task. For prompts above 272,000 tokens, calculate the long-context charge first. Start with the AI/ML API request above, then adapt it to a deliverable from your own workflow.
For the other model in this release, see our GPT-6.2 Sol vs Claude Opus 5.5 guide.