Grok 4 API

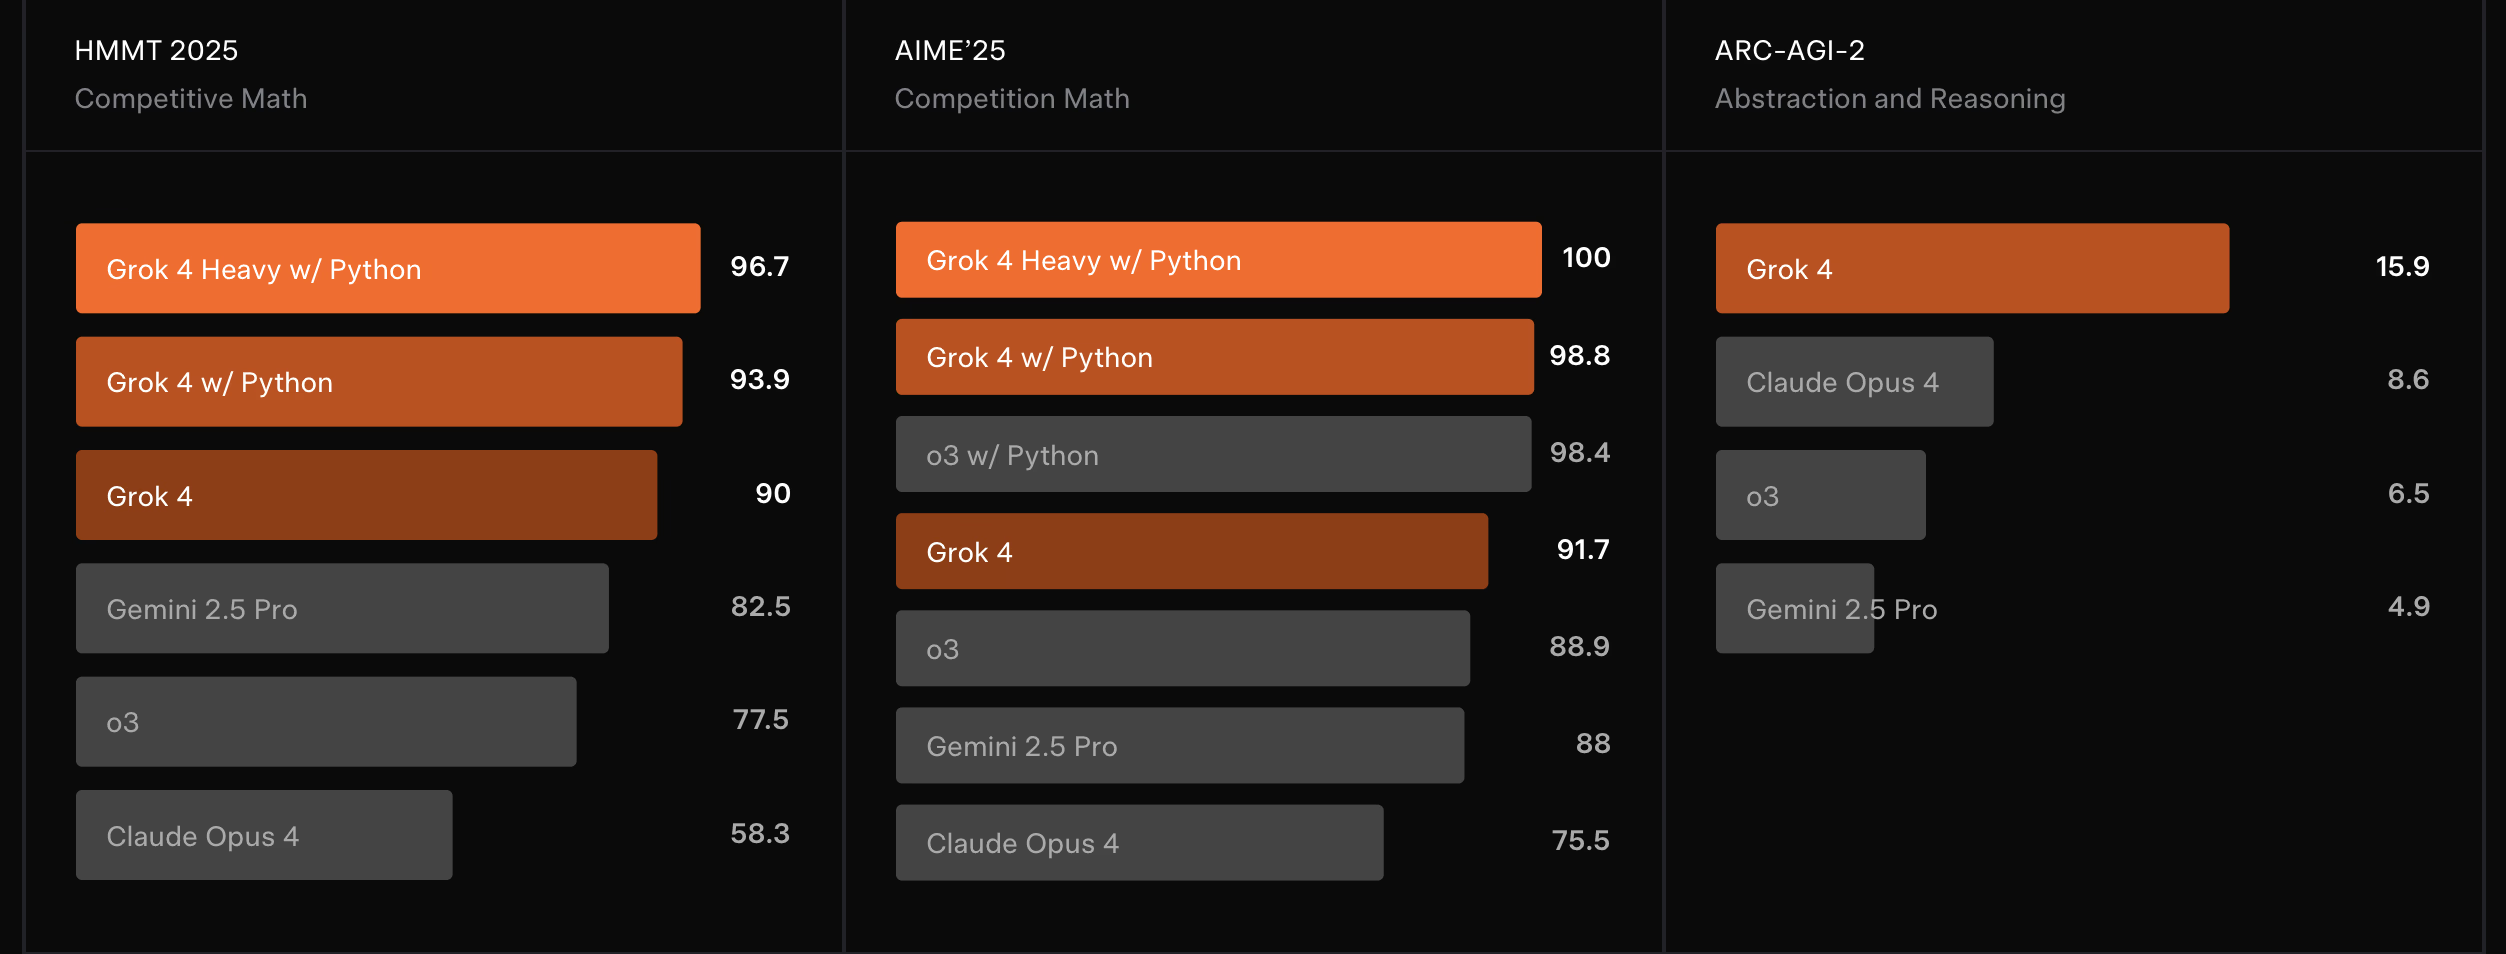
Grok 4 is designed for advanced reasoning and complex tool‑use workflows. Built on the Grok 3 architecture with 10× more reinforcement learning compute, it sets state‑of‑the‑art scores on tasks like ARC-AGI‑2, AIME25, and Humanity’s Last Exam (HLE).
Output

Overview

xAI Grok 4 Description

Grok 4 is the latest large language model from xAI, designed for high-level reasoning, agentic behavior, and real-world task automation. It builds upon Grok 3’s architecture, but trains reasoning with 10× more compute and integrates tool use directly into its RLHF pipeline.
Technical Specification

Performance Benchmarks

  • Context Window: 256,000 tokens
  • Max Output: ~4,096 tokens
  • Training Regime: 10× more RL compute than Grok 3
  • Tool Use: Native, with strong multi-step support

Performance Metrics

  • SOTA on ARC-AGI-2: 15.9%
  • AIME 2025: 76.9% accuracy
  • Humanity’s Last Exam (HLE):
    • With tools: 44.4% overall, 50.7% on text-only section
    • Without tools: 25.4% (vs 21.6% Gemini 2.5 Pro)
Metrics

Key Capabilities

  • Multi-step reasoning across long contexts
  • Native tool-use through real/synthetic environments
  • Deterministic outputs (non-streamed)
  • Planning with API execution
  • Robust performance on AGI-style benchmarks

API Pricing

Input: 0–128k: $3.9; 128k+: $7.8

Output: 0–120–128k: $19.5; 128k+: $39

Code Samples

Comparison with Other Models

  • vs. GPT‑4o: GPT‑4o leads in multimodality and web browsing. Grok 4 offers better reasoning performance and tool integration in AGI-style tasks.‍
  • vs. Claude 4 Opus: Claude 4 excels in language safety and alignment. Grok 4 outperforms on ARC-AGI-2 (15.9% vs 8.6%) and HLE, especially in tool-enabled setups.‍
  • vs. Gemini 2.5 Pro: Gemini is strong in speed and instruction following. Grok 4 surpasses in zero-shot reasoning and planning (HLE 25.4% vs 21.6% without tools).
  • vs. Grok 3: Grok 4 is a major upgrade over Grok 3, trained with 10× more RL compute and native tool-use instruction. It achieves 25.4% on Humanity’s Last Exam without tools (vs. Grok 3’s ~14.7%), and delivers better multi-step reasoning and factual recall.

Limitations

  • Text-only (no vision/audio support as of Grok 4)
  • Tool use not compositional (sequential only)
  • Closed-weight model
  • Seed determinism may be unreliable in streaming
  • No public inference locally or offline

API Integration

Accessible via AI/ML API. Sign up here.

Use cases

  • Academic Benchmarking: High performance in math, logic, and abstract reasoning tasks.
  • Long-Context Summarization: Handles documents and threads with extreme context.
  • Research Prototyping: Ideal for technical exploration and agent design.
  • Competitive Analysis: For evaluation against frontier reasoning models.

How to use Grok 4 API

Install any OpenAI-compatible SDK, point it at api.aimlapi.com/v1, and set the model to .

OpenAI-compatible — swap the base URL and it works with your existing SDK.

Grok 4 API Pricing

TypePrice
Input
Output

Grok 4 Benchmarks

BenchmarkScoreWhat it measuresSourceRetrieved
Intelligence
22.5
Composite score across standardised reasoning, knowledge and problem-solving evaluations, measured independently by Artificial AnalysisSourceSeptember 12, 2026
Math
92.7
Composite score across standardised mathematics evaluations, measured independently by Artificial AnalysisSourceSeptember 12, 2026

Grok 4 vs other models

ModelInputOutputContextBest for
Grok 4
This page
$6.5 / 1M tokens
$39 / 1M tokens
1M tokens
Reasoning + agents
$2.6 / 1M tokens
$13 / 1M tokens
1M tokens
Balanced coding + agents
$3.9 / 1M tokens
$19.5 / 1M tokens
1M tokens
Long-context, multimodal & agentic workflows
$1.95 / 1M tokens
$11.7 / 1M tokens
1M tokens
Reasoning + agents

Frequently asked questions

Yes, Grok 4 can stream responses as they are generated.

Yes, Grok 4 supports function calling.

Grok 4 was built by xAI .

Yes, Grok 4 supports reasoning as one of its listed capabilities.

Start building with Grok 4

Get API Key
1000+ models, one API.
