Llama 3.1 Nemotron 70B Instruct is a sophisticated large language model developed by NVIDIA, designed to enhance the performance of instruction-following tasks. It utilizes advanced training techniques and a robust architecture to generate human-like responses across a variety of applications.
The model is intended for applications such as virtual assistants, customer service bots, content generation, and educational tools where accurate and coherent instruction following is critical.
Llama 3.1 Nemotron 70B Instruct can be used for patient education since it excels at following complex instructions due to its reinforcement learning from human feedback, ensuring accuracy in patient assessments and medical inquiries. Learn more about this and other models and their applications in Healthcare here.
Llama 3.1 Nemotron supports multiple languages, making it suitable for diverse global applications.
The model is based on the Transformer architecture, which allows it to effectively capture long-range dependencies in text. Key architectural details include:
Llama 3.1 Nemotron was trained using a combination of supervised learning and reinforcement learning from human feedback (RLHF).
As of October 2024, Llama 3.1 Nemotron has achieved impressive performance metrics:
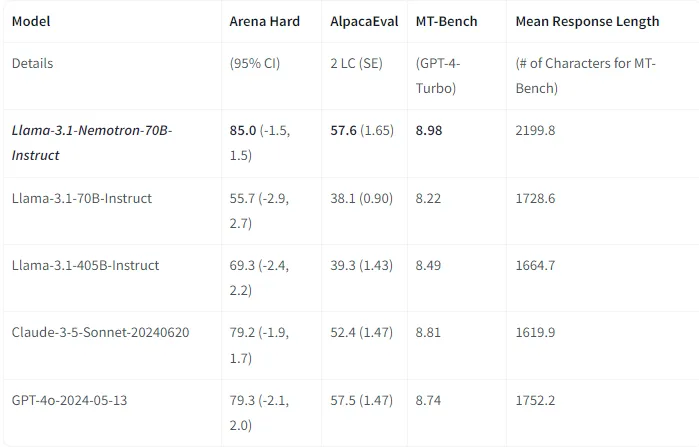
As of 1 Oct 2024, Llama-3.1-Nemotron-70B-Instruct performs best on Arena Hard, AlpacaEval 2 LC (verified tab) and MT Bench (GPT-4-Turbo)
The model is available on the AI/ML API platform as "Llama 3.1 Nemotron 70B Instruct" .
Detailed API Documentation is available here.
NVIDIA emphasizes ethical considerations in AI development by promoting transparency regarding the model's capabilities and limitations. They encourage users to adhere to responsible usage guidelines to prevent misuse or harmful applications.
Llama 3.1 Nemotron is licensed under a proprietary license allowing both commercial and non-commercial usage rights with specific restrictions on redistribution.
Get Llama 3.1 Nemotron 70B Instruct API here.
OpenAI-compatible — swap the base URL and it works with your existing SDK.
| Type | Price |
|---|---|
| Input | |
| Output | |
| Benchmark | Score | What it measures | Source | Retrieved |
|---|---|---|---|---|
| Intelligence | 6.9 | Composite score across standardised reasoning, knowledge and problem-solving evaluations, measured independently by Artificial Analysis | Source | September 22, 2026 |
| Math | 11 | Composite score across standardised mathematics evaluations, measured independently by Artificial Analysis | Source | September 22, 2026 |
| Model | Input | Output | Context | Best for |
|---|---|---|---|---|
Llama 3.1 Nemotron 70B Instruct This page | ||||
| Reasoning + agents | ||||
| Balanced coding + agents | ||||
| Long-context, multimodal & agentic workflows | ||||
| Reasoning + agents |
Yes, Llama 3.1 Nemotron 70B Instruct can stream responses as they are generated.
Yes, Llama 3.1 Nemotron 70B Instruct supports both function calling and structured outputs.
Llama 3.1 Nemotron 70B Instruct was built by NVIDIA.
No. Its listed capabilities are function calling, streaming, and structured outputs, with no image input support.
It is accessed via the v1/chat/completions endpoint.






